The Agentic Web
AI Agents Shouldn’t Have to Reverse-Engineer Every Website
What I learned while building an open-source tool to make existing web apps easier for AI agents to understand
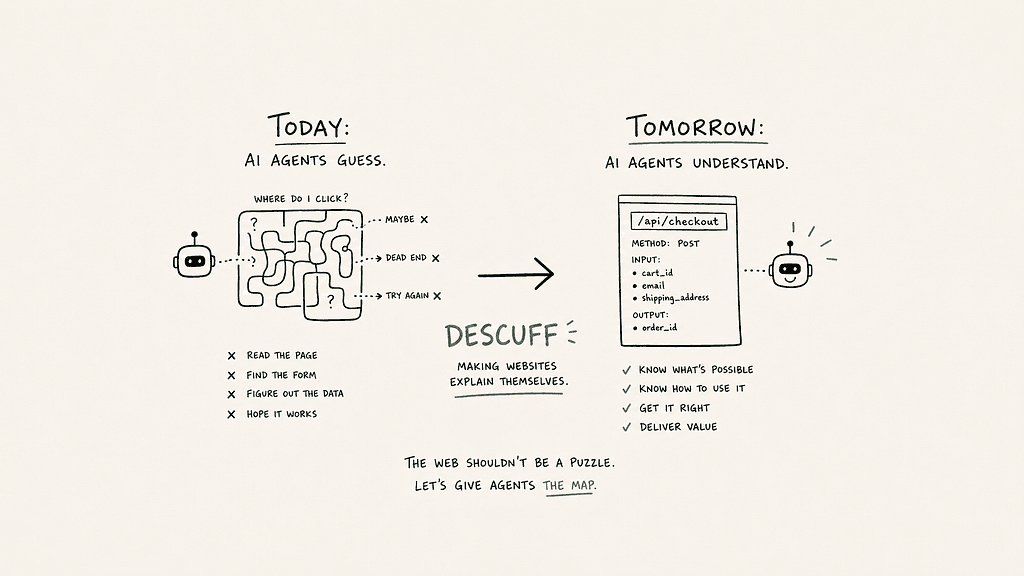
Give a capable AI agent a fairly ordinary task:
Find a black hoodie under £60, check whether medium is available, and add it to the basket.
It can probably get surprisingly far. The agent can inspect the page, find search, interpret the results, open a product, locate the size selector and eventually work out which button adds the item to the basket.
That is genuinely impressive. But there is also something slightly strange about the process.
The application already knows that the object on screen is a product. It knows its price, its available sizes and whether it is in stock. It knows how search works and what happens when something is added to a basket. Somewhere underneath the interface, there may already be functions or endpoints that amount to:
Yet an AI agent may still have to reconstruct those capabilities from an interface designed for a person.
What if the application could explain itself?
The web is very good at explaining itself to us
Humans have spent decades learning the language of websites. A large text field near the top of a shop is probably search. A shopping-bag icon probably leads to a basket. A red button labelled “Delete account” deserves more caution than a small “Learn more” link.
Most of this barely feels like reasoning anymore. We understand menus, forms, buttons, icons, tabs and visual grouping because web interfaces have evolved around human expectations.
AI agents have inherited that same environment.
Google’s current guidance for agent-friendly websites describes screenshots, raw HTML and the accessibility tree as important ways an agent may understand a page. Modern systems can combine these signals, but visual analysis can be slower and relatively expensive in token usage (Kulikowski and More, 2026).
There is also the simple problem of how much information a page can expose. FocusAgent, a 2025 research project, describes web-agent observations that can run into tens of thousands of tokens. Its researchers reduced accessibility-tree observation size by more than 50% while maintaining performance comparable with strong baselines on WebArena and WorkArena (Kerboua et al., 2025).
That suggests something slightly counter-intuitive: better agent interfaces may not always be about giving the model more context. Sometimes the useful thing is giving it less, but more relevant, context.
Machine-facing interfaces can help
There is evidence that this can make a practical difference.
Song et al. (2025) tested three approaches on WebArena: an agent working through the browser, an agent using APIs, and a hybrid agent able to use both.
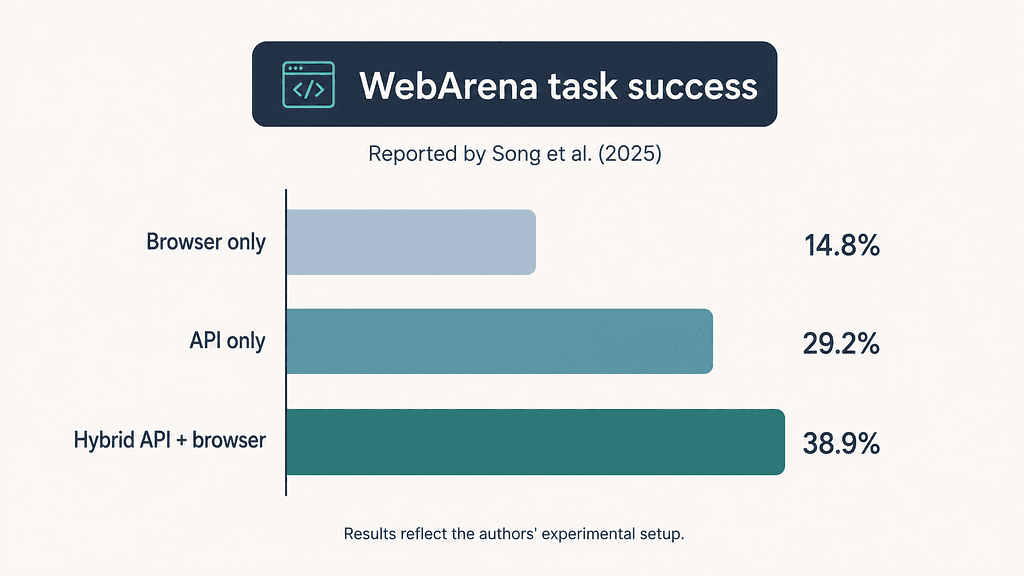
The browsing agent achieved 14.8% average task success. The API-based agent reached 29.2%, while the hybrid approach achieved 38.9%.
The point is not that APIs are always better than browsers. It is that once the machine had access to an interface designed for machines, the result changed substantially. More interestingly, the strongest system was the hybrid one.
That feels like an important clue. The browser can remain the universal fallback, while structured interfaces handle capabilities that can be exposed more directly and reliably.
Token cost tells a similar story. Cloudflare’s Markdown for Agents feature allows an enabled site to respond with Markdown when an agent requests text/markdown, rather than returning the normal HTML representation. In Cloudflare's documented example, a page estimated at 12,345 tokens in its original form became 725 tokens as Markdown, roughly a 94% reduction for that particular page (Cloudflare, 2026).
That number should not be treated as representative of every website. But the principle is useful: machines do not necessarily need every part of the interface that humans and browsers do.
A machine-facing layer is already starting to appear
When I first started thinking about this problem, I assumed solving it might require inventing a new format. The more I looked into it, the less appealing that seemed.
A number of existing standards and newer proposals already cover different pieces of the problem. OpenAPI gives machines a structured description of HTTP APIs. RFC 9727 adds a standard /.well-known/api-catalog location intended to make published APIs easier to discover automatically (Smith, 2025). Schema.org and JSON-LD can describe entities such as products, organisations, articles and events.
Then there is llms.txt, a community proposal for providing language models with a concise Markdown entry point into a site. The proposal reached a second version in August 2026, and its author reports adoption across thousands of sites as well as support from documentation platforms and tooling (Howard, 2026). It is not an IETF standard, but the level of experimentation around it is still interesting.
Chrome is exploring something more actionable through WebMCP. Instead of an agent looking at a form and guessing what it does, a page can expose a named tool with a description and structured inputs. Chrome opened a WebMCP origin trial in June 2026, and Lighthouse now includes tooling for inspecting registered WebMCP tools (Klepper, 2026).
Taken individually, none of these technologies is “the agentic web”. Together, though, they suggest that a machine-facing layer is beginning to form alongside the normal human-facing web.
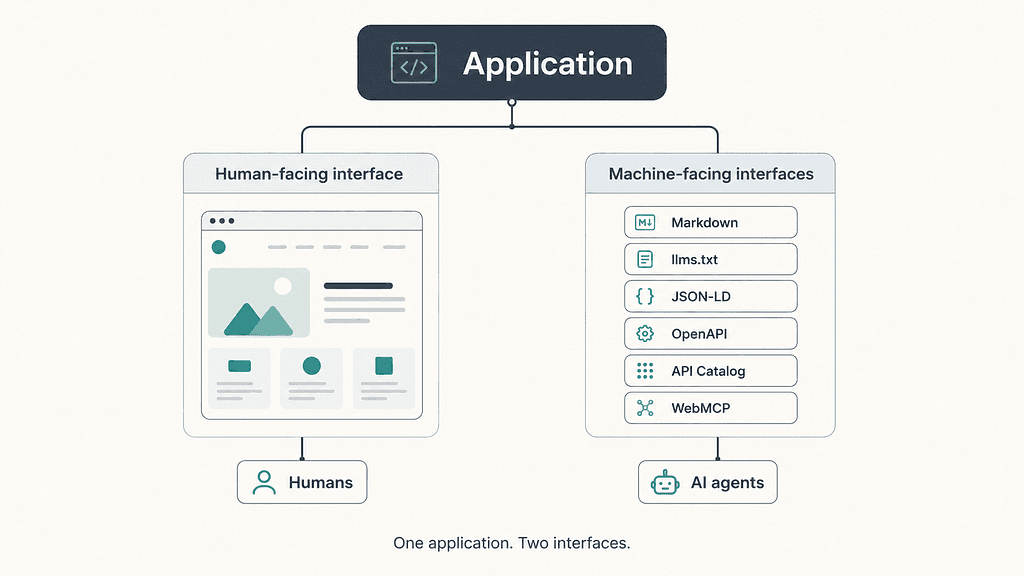
That layer probably should not look identical for every website. A documentation site might benefit from Markdown and llms.txt, while an API-heavy application may be better served by OpenAPI and API Catalog. A transactional product could eventually expose a small number of carefully selected tools, whereas a simple static website may need almost nothing beyond the semantic structure it already has.
This is why I don’t think being “agent-ready” should mean generating every AI-related file currently trending on GitHub.
The useful question is much more specific:
What does this particular application actually need?
Existing software is the harder problem
It is relatively easy to design a new application with machine-facing interfaces in mind. Most software, however, already exists.
A mature SaaS product may contain years of accumulated routes, APIs, authentication, forms, permissions, Server Actions, schemas, billing flows and business logic. Much of the information an agent would want is already somewhere inside that application; it is simply expressed through implementation rather than through one explicit machine-facing contract.
That was the question that eventually became Descuff:
Can we understand an existing application well enough to help it expose the right parts of itself through the standards that already exist?
Descuff is an open-source experiment in approaching agent readiness from the application itself. The current public preview focuses on Next.js, where it can inspect routes, API handlers, Server Actions, forms, authentication boundaries and existing machine-facing standards.
The important part, though, is the separation between evidence and interpretation.
A static analyser can confidently establish that POST /api/slots/query exists. It cannot automatically know that the operation means check_availability, nor can it decide purely from the route name whether an autonomous agent should be allowed to call it. Those are different questions.
The workflow therefore tries to move from structural evidence, to semantic understanding, to implementation, and finally to independent validation.
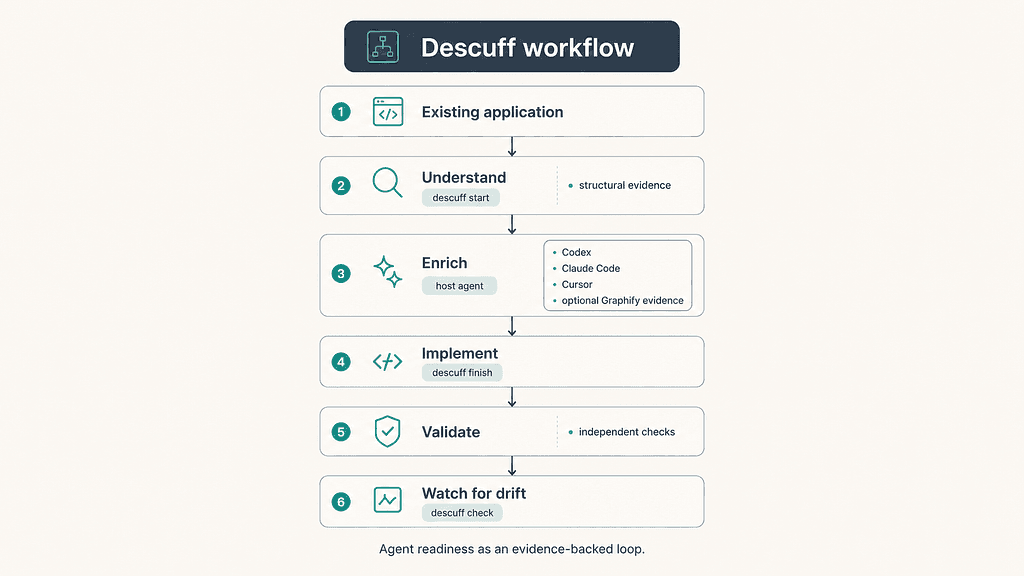
Recent versions also let coding agents such as Codex, Claude Code and Cursor participate in semantic enrichment and implementation. Importantly, that does not mean Descuff secretly sends the codebase to another model and accepts whatever comes back. The host agent receives an evidence packet, produces semantic enrichment, and Descuff validates the resulting structure before it is accepted.
There is also now a continuous-readiness layer. After an application has been processed, Descuff can record a baseline and later use descuff check to identify changes that may have caused its machine-facing contracts to drift away from the application itself.
That matters because generating an OpenAPI document once is the easy part. Keeping it truthful six months later is much harder.
Real applications broke the nice assumptions
One of the easiest ways to make a code-analysis project look intelligent is to test it only on applications created specifically for the project.
So I tried the opposite.
I selected eight unrelated public Next.js repositories covering very different shapes of software: a static/marketing site, a content site using the Pages Router, ecommerce, SaaS with authentication and Stripe, booking workflows, an authenticated Pages Router application, an API-heavy analytics product and a large forms-heavy monorepo.
The first recorded external audit found 11 concrete issues: nine major and two minor. These included missed Server Actions, incorrect authentication assumptions, bad standards recommendations, monorepo discovery failures, classification errors, validation false positives and unsupported Next.js patterns (Descuff, 2026).
A few of those failures changed how I thought about the project.
A checkout route does not make an application ecommerce
One SaaS starter contained Stripe checkout functionality. An early classifier saw the checkout evidence and concluded that the application was ecommerce.
The pattern match was understandable; the conclusion was wrong.
Real applications rarely belong to one neat category. SaaS products contain payments, content sites contain authentication, and ecommerce applications can contain editorial workflows. Descuff therefore had to become less dependent on one application-wide label and more interested in the actual capabilities present.
GET does not mean public
Another failure involved read operations associated with teams and users. Because they were GET endpoints, an early interpretation treated them as public reads.
They were authenticated.
That forced authentication evidence to become part of capability classification rather than treating the HTTP method as a shortcut for deciding visibility or risk.
Sometimes the right recommendation is nothing
A mostly static website exposed a different failure. Descuff recommended OpenAPI, API Catalog and WebMCP even though the application had no meaningful API or agent-callable workflow that justified them.
Technically, it could generate the files.
It just shouldn’t.
The correct fix was not to build another generator. It was to make Descuff better at recommending less.
That lesson is probably more important than it sounds. If an ordinary static website already communicates what it needs to communicate through semantic HTML and structured content, a useful agent-readiness tool should be willing to leave it alone.
After those findings were turned into fixes and regression cases, the recorded audit snapshot contained 24 manually selected expected capabilities across the eight repositories. All 24 were detected in the rerun, with no recorded invented capabilities in that particular snapshot (Descuff, 2026).
That is not evidence that Descuff has 100% accuracy. Twenty-four manually selected capabilities across eight repositories are nowhere near enough to support a claim like that.
What it does show is that testing against external software revealed assumptions that controlled fixtures had not, and those assumptions could be turned into concrete improvements.
There is still a lot more testing to do.
Descuff is open source, so the analyser, generated artefacts, tests and current implementation are all available on GitHub.
The browser is not going away
None of this makes me think browser agents are a mistake. Quite the opposite: browser interaction solves an extraordinary compatibility problem because it gives agents a universal way to interact with software that was never designed for them.
If a website exposes no structured machine interface, the browser still works. If a workflow is unusual or only represented through the UI, browsing may still be the correct approach.
The WebArena result is interesting precisely because the strongest agent was hybrid, not API-only (Song et al., 2025).
A useful future may therefore look less like “APIs versus browsers” and more like a hierarchy: use a reliable structured capability when one exists, use structured content or APIs where appropriate, and fall back to browser interaction when necessary.
Lù et al. (2025) make a broader version of this argument in their position paper Build the Web for Agents, Not Agents for the Web. Their point is that we should not place the entire burden on increasingly capable agents to interpret interfaces designed for humans; we can also think about interfaces designed specifically for machines.
Descuff is not an implementation of that paper. The question I find interesting is the developer-tooling version of the same problem:
If the web moves in this direction, how does all the software that already exists get there?
The application already contains much of the answer
A mature application already contains a surprisingly rich description of itself; that description is simply spread across the codebase. Routes reveal reachable surfaces, types and schemas describe data, middleware and permissions reveal boundaries, while forms, Server Actions and APIs expose inputs and behaviour.
Tests provide another layer by describing expected outcomes, and runtime behaviour tells us what the software actually does rather than what the source code merely appears to do.
In other words, developers already encode much of the information an agent would want to know. We just encode it primarily for frameworks, runtimes and other developers rather than presenting it as one coherent machine-facing description.
I do not think that means websites disappear or that every application suddenly becomes an API. A machine-facing interface can sit beside the human one in the same way an API can sit behind a graphical application: two views of the same underlying software for different consumers.
The individual standards will change. WebMCP may evolve substantially. llms.txt may or may not become important. New approaches will appear and some current ones will probably disappear.
That is why the part of Descuff I find most interesting is increasingly not the generation of any particular standard. The more durable problem sits further upstream: understanding what an application actually does, deciding what it can safely expose, mapping that understanding to appropriate interfaces, and keeping those interfaces accurate as the software changes.
The web has spent decades becoming better for humans. That work should continue. Accessibility matters, semantic HTML matters, and good UX matters.
AI agents are simply becoming another consumer of software and they are not humans.
Maybe the future is not only about building agents that become infinitely better at reverse-engineering every interface we create. Maybe part of it is building software that becomes better at explaining itself.
That is the idea I am exploring with Descuff.
For now, I mostly want to see where it breaks.
Descuff is open source. You can explore the project and its experiments or view the source on GitHub.
References
- Cloudflare (2026) Markdown for Agents. Cloudflare Fundamentals. Last updated 13 July 2026. Accessed 30 August 2026.
- Descuff (2026) Descuff Changelog. Descuff. Accessed 30 August 2026.
- Howard, J. (2026) The /llms.txt file, v2. Originally published 3 September 2024; modified 10 August 2026. Accessed 30 August 2026.
- Kerboua, I., Omidi Shayegan, S., Thakkar, M., Lù, X.H., Boisvert, L., Caccia, M., Espinas, J., Aussem, A., Eglin, V. and Lacoste, A. (2025) ‘FocusAgent: Simple Yet Effective Ways of Trimming the Large Context of Web Agents’, arXiv, 2510.03204.
- Klepper, A. (2026) ‘Join the WebMCP origin trial’, Chrome for Developers, 9 June. Accessed 30 August 2026.
- Kulikowski, K. and More, O. (2026) ‘Build agent-friendly websites’, web.dev. Accessed 30 August 2026.
- Lù, X.H., Kamath, G., Mosbach, M. and Reddy, S. (2025) ‘Build the Web for Agents, Not Agents for the Web’, arXiv, 2506.10953.
- OpenAPI Initiative (2025) OpenAPI Specification 3.2.0. Linux Foundation. Accessed 30 August 2026.
- Smith, K. (2025) RFC 9727: api-catalog: A Well-Known URI and Link Relation to Help Discovery of APIs. Internet Engineering Task Force.
- Song, Y., Xu, F.F., Zhou, S. and Neubig, G. (2025) ‘Beyond Browsing: API-Based Web Agents’, Findings of the Association for Computational Linguistics: ACL 2025, pp. 11066-11085. doi:10.18653/v1/2025.findings-acl.577.